开放模型推理市场如今有多大?Interconnects 用 token 数据测算
Interconnects 利用 Baseten、Fireworks、Together AI 及 OpenRouter 的 token 数据测算并分析了开放模型推理市场的规模与增长情况。其中,Fireworks 在公司首届会议上宣布其为客户定制模型提供每日超过 40T tokens 的服务,且该垂直业务自今年夏天以来增长超过 2 倍。这些公开披露的数据显示,开放模型推理正呈现接近指数级的增长态势。
My longest running agent testbed has been building the Interconnects Dashboard — an aggregator of all of the best data on open model adoption and performance from across the web. This dashboard is freely available and becoming quite useful. Still, all the measurements we have on open model adoption are incredibly imprecise. We have noisy platform metrics, marketing-related metrics from startups, and imperfect public evaluations. It takes an informed eye to figure out where things are going. These research notes are my current best approximations of where we stand.
As with most things on Interconnects, our goal is to build well more value than we capture, so the data on the dashboard will remain free for the foreseeable future. These notes will be more raw than many of my articles, a place for sharing what I’m mulling over but don’t have complete evidence for (yet). They will be primarily paid, enabling me to speak more freely. If you work in AI policy or policy-facing research, please reach out to us and we can likely get discounted or free access.
The primary question I wanted to address today is: What is the market for open model inference? Is it growing? Is it a rounding error relative to OpenAI/Anthropic?
I’ve been building the best measurements I can here, primarily using the open model inference startups Baseten, Fireworks, and Together AI as the bellwethers here (along with the open model share of OpenRouter’s token volume, which they thankfully report in their API). The hyperscalers also likely have a major footprint here, e.g. Amazon Bedrock and Azure’s model garden, but I haven’t seen them break down usage by model category. The startups’ fates are much more directly correlated with the success of open model inference as a category.
For the latest data, we can start with a slide from my talk on the open model economy (recording here). These are the public disclosures from the open model startups on their token volume, over time, log-scale.
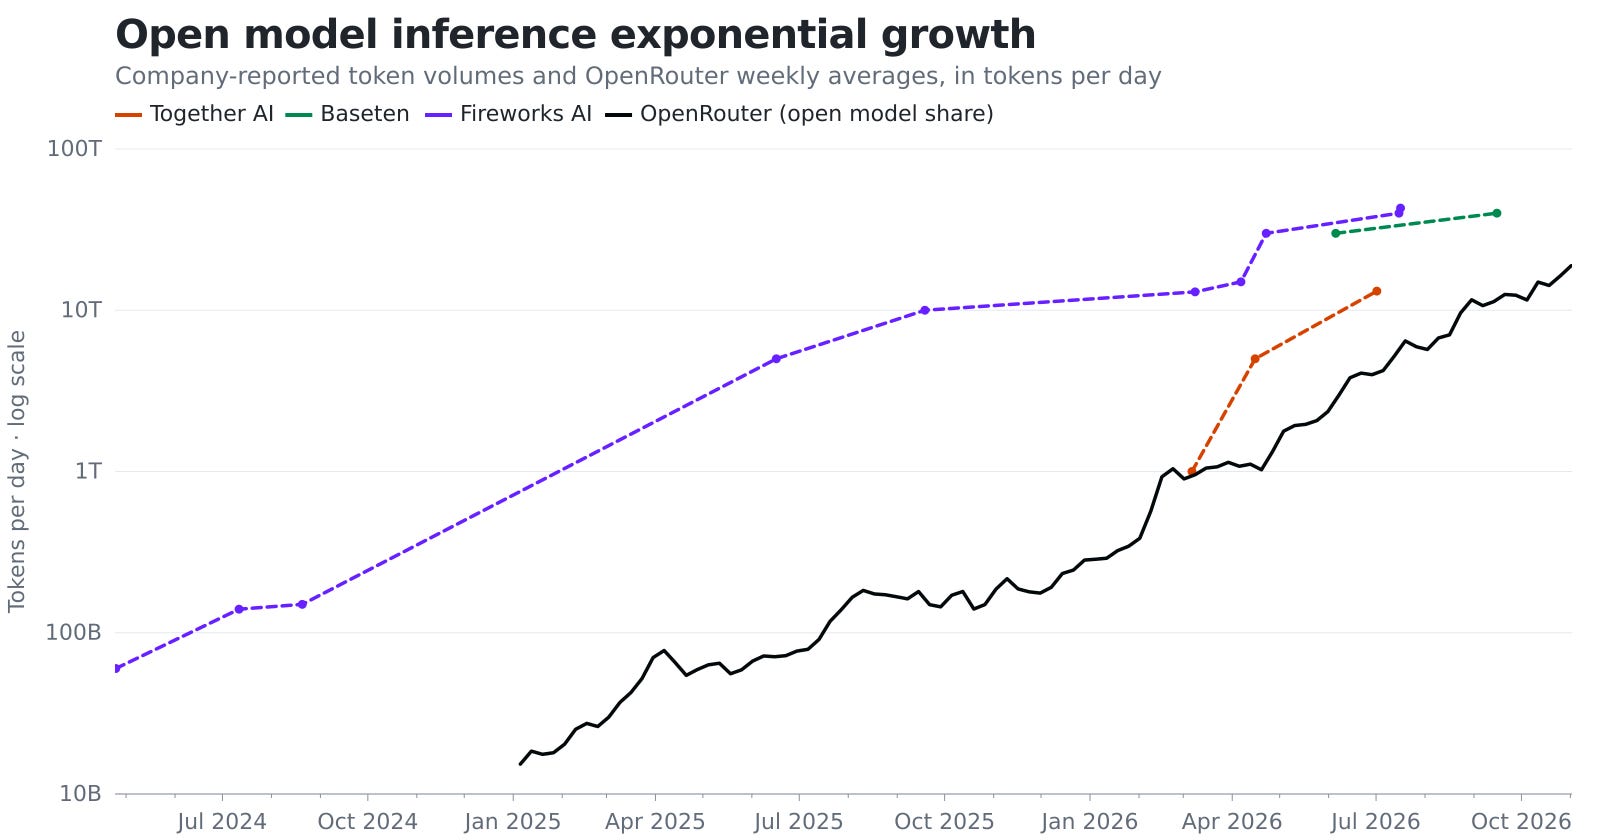
This shows near-exponential growth, before the uptick that would follow GLM 5.2’s step change in open agents. For example, Fireworks announced at their first company conference this week that they’re serving more than 40T tokens per day to customers’ customized models. This is just one slice of their inference, a vertical that they said grew over 2x from this summer, so I would expect their total number this fall to be well above 100T tokens when we get the next update.
My first instinct with these numbers has been to ground them versus any closed model or hyperscale company we can, at least in terms of token volume. Thankfully, Google releases token volumes for the entire platform and API usage in their earnings reports. We can overlay those two numbers on top of the open model inference platforms, with the resulting plot below:
来源:Nathan Lambert:Interconnects · interconnects.ai